Choosing among the top GPU Rental Services is not simply a matter of finding the fastest graphics card. Real performance depends on workload design, software compatibility, network speed, storage, and billing rules. A powerful NVIDIA H100 may accelerate model training, while a lower-cost RTX 4090 could suit image generation, rendering, or development testing. The right option depends on the task.
Costs vary. Details matter.
This guide examines leading providers through practical, measurable criteria. These include GPU availability, hourly pricing, regional coverage, uptime history, container support, data protection, and technical assistance. It also considers whether users can pause instances, attach persistent storage, or scale across multiple GPUs without complicated configuration. Public benchmarks help, but they do not tell the whole story. A provider may advertise impressive performance while delivering inconsistent access during peak demand.
Reliable decisions require careful verification. Readers should review current pricing pages, service-level terms, hardware specifications, and independent customer feedback before committing resources. Some platforms offer flexible pay-as-you-go access, while others provide reserved capacity for teams with predictable workloads. Neither model is universally better. A cheap instance can become expensive when idle time, data transfer, and setup delays are included.
The comparison may contain unavoidable limitations. GPU inventories change quickly, regional prices fluctuate, and benchmark results can vary between software versions. That uncertainty deserves attention. By separating marketing claims from practical evidence, this overview helps researchers, developers, studios, and businesses identify GPU Rental Services that match their technical needs, risk tolerance, and budget.
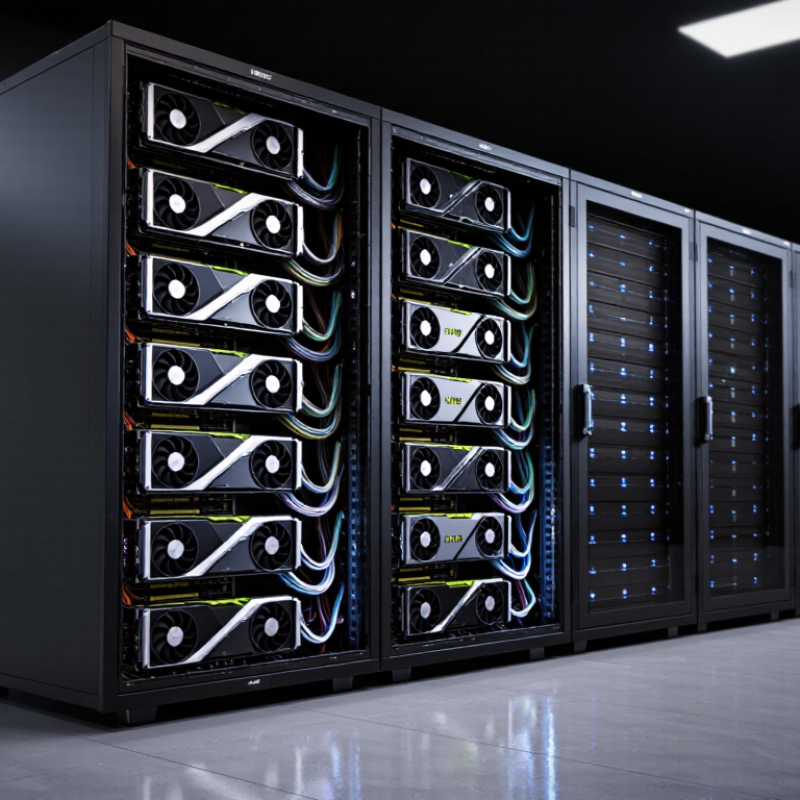
GPU rental services provide temporary access to powerful graphics processors through remote cloud infrastructure. Users rent computing capacity instead of purchasing expensive hardware. This model supports artificial intelligence training, video rendering, scientific simulations, and 3D design. For a small team, renting can reduce upfront costs and avoid a hot, noisy server room. It also allows projects to scale during busy periods. Still, the cheapest hourly rate is not always the best value.
Core features include flexible billing, multiple GPU configurations, secure remote access, and fast deployment. Clear pricing matters. Users should check storage, data transfer, minimum rental periods, and shutdown policies before starting a workload. A reliable service should provide current GPU specifications, realistic performance information, and visible availability. Network speed also affects results, especially when datasets are large. Strong access controls and encrypted connections help protect private project files.
When comparing top GPU rental services, I would test a small workload before committing to a long contract. Measure startup time, training speed, stability, and total cost. A service may advertise impressive hardware but perform poorly under heavy demand. That is easy to overlook. In practice, support quality can matter as much as raw processing power. Clear documentation, usage alerts, and honest outage reporting signal professional operations. My evaluation would not be perfect, because performance changes with region, software settings, and workload design. These limits should remain visible when making a technical decision.
GPU rental services provide on-demand access to accelerators without requiring organizations to purchase and maintain hardware. These representative memory tiers, commonly found across rental marketplaces, show how available capacity increases from lightweight inference and development workloads to large-scale AI training, scientific computing, and high-memory data processing. More VRAM generally allows larger models, datasets, and batch sizes to run on a single accelerator.
When comparing GPU rental providers, price per hour is only the visible number. A cheaper instance may deliver less memory, slower storage, or weaker network throughput. Record the GPU model, VRAM, interconnect, region, and billing unit before testing. Run the same workload for at least one hour. Measure completed jobs, not advertised peak speed. A useful score combines performance, availability, egress fees, setup time, and support response. Small billing rules can change a monthly estimate dramatically.
Reliability needs evidence. Uptime Institute’s 2024 Global Data Center Survey reported that 54% of respondents said their latest outage cost more than $100,000. Around 20% reported losses above $1 million. Ask for historical uptime, incident communication, spare capacity, and recovery targets. A status page is useful, but it is not proof. Check data isolation, encryption, deletion procedures, and access controls. These details matter when models process confidential business information.
Energy deserves a place in the comparison. The International Energy Agency’s Electricity 2024 report estimates that data centers consumed about 415 TWh globally in 2024. That figure could exceed 945 TWh by 2030. Providers should disclose power sources, cooling practices, and regional efficiency data. Carbon claims can hide important differences. No scorecard is perfect. I would test two providers with identical workloads, then compare invoices against the original estimate. That final check often exposes assumptions that marketing pages leave unclear.
GPU rental services now follow several practical models. On-demand cloud instances suit short experiments, emergency capacity, and changing workloads. Users pay hourly and can stop machines after a training run. Bare-metal rentals offer direct hardware access, stable performance, and fewer virtualization concerns. They work well for large model training, simulations, and video processing. However, setup can take longer. That delay is easy to underestimate.
Reserved capacity lowers prices for teams with predictable demand. It fits monthly research programs, production inference, and repeated fine-tuning. Managed GPU platforms add container setup, monitoring, storage, and deployment tools. These services help smaller engineering teams avoid spending days on configuration. Serverless inference is different. It charges by usage, often with automatic scaling. This model suits APIs with uneven traffic, though cold-start delays may affect interactive applications. IDC’s Worldwide AI and Generative AI Spending Guide projects related spending will reach 632 billion dollars by 2028. Demand will not make every rental model efficient. The right choice still depends on workload duration, memory needs, data movement, and response targets. Uptime Institute’s 2024 Global Data Center Survey also highlights rising power and operational pressures, which can influence availability and pricing. I would benchmark three workloads before committing. The lowest hourly rate can lose money when data transfers, idle time, or failed jobs accumulate. Small tests reveal uncomfortable details.
A practical comparison of major GPU rental service models, typical hardware options, and suitable workloads.
| Service model | Typical GPU configuration | Billing pattern | Best uses | Main advantages | Important considerations |
|---|---|---|---|---|---|
| On-demand GPU instances | Single GPUs or small multi-GPU virtual machines, commonly with 16–80 GB of GPU memory per accelerator. | Per second, per minute, or per hour; usually no long-term commitment. | Interactive development, short experiments, inference APIs, testing, and variable workloads. | Fast provisioning, flexible capacity, and payment based on actual usage. | Hourly rates can be higher than committed capacity; availability may vary by region and GPU type. |
| Reserved GPU capacity | Dedicated GPU instances or fixed clusters reserved for a defined period, often from one month to several years. | Discounted fixed commitment or prepaid term. | Stable production inference, recurring model training, and predictable enterprise workloads. | More predictable access and potentially lower effective cost for sustained utilization. | Requires accurate demand forecasting and may create unused capacity during quiet periods. |
| Spot or interruptible GPU instances | Temporary access to unused GPU capacity, ranging from a single accelerator to distributed clusters. | Variable or auction-based pricing, generally below standard on-demand rates. | Checkpointed training, batch rendering, simulations, and fault-tolerant research jobs. | Low cost and access to otherwise unused infrastructure. | Instances can be stopped with limited notice; workloads need checkpointing and restart automation. |
| Managed GPU clusters | Multi-node clusters with high-speed networking, shared storage, schedulers, monitoring, and container support. | Hourly cluster billing, monthly contracts, or project-based pricing. | Large-scale model training, distributed computing, scientific research, and high-performance analytics. | Reduces infrastructure administration and supports coordinated multi-GPU jobs. | Higher minimum spend, more complex job configuration, and possible data-transfer charges. |
| Bare-metal GPU servers | Physical servers with one or more dedicated GPUs, direct hardware access, and configurable operating systems. | Hourly, daily, or monthly rental; often priced per physical server. | Performance-sensitive training, custom drivers, graphics workloads, and applications requiring hardware control. | Consistent performance, strong isolation, and fewer virtualization limitations. | Slower provisioning than virtual machines and less flexibility when scaling by small increments. |
| GPU containers and development workspaces | Containerized environments with preconfigured frameworks, notebooks, drivers, and selected GPU access. | Per GPU-hour, workspace-hour, or subscription-based pricing. | Prototyping, education, data science, reproducible experiments, and team collaboration. | Quick setup, consistent software environments, and reduced dependency management. | Less operating-system control and possible limits on custom networking or low-level configuration. |
| GPU-as-a-Service APIs | Serverless or semi-managed GPU endpoints that expose inference, image generation, speech, or video functions through APIs. | Per request, per second, per token, per image, or per processing unit. | Production inference, content applications, automated media processing, and event-driven workloads. | Minimal infrastructure management and automatic scaling for changing demand. | Less control over hardware and runtime; pricing depends heavily on request volume and execution time. |
| Colocation or dedicated GPU hosting | Customer-owned or long-term leased GPU servers installed in a professionally managed data center. | Monthly rack, power, network, and support fees; hardware may be purchased separately. | Continuous high-utilization workloads, regulated data processing, and long-lived private infrastructure. | Strong control, predictable physical capacity, and potential data-residency benefits. | Higher upfront investment, hardware maintenance responsibilities, and limited short-term elasticity. |
Selection guide: Choose on-demand capacity for flexibility, reserved capacity for predictable utilization, interruptible capacity for price-sensitive fault-tolerant jobs, managed clusters for distributed workloads, and GPU APIs for applications that need inference without managing servers.
Choosing among GPU rental services requires more than comparing hourly rates. In a practical benchmark, record the exact GPU model, memory size, region, and billing unit. Public 2024 cloud pricing surveys show large differences, often exceeding 50% for similar accelerator classes. Spot pricing can reduce costs further, but interruptions may erase those savings. Watch the minimum rental period, storage fees, data-transfer charges, and idle billing.
Performance needs independent evidence. MLPerf Inference v4.1 reported substantial variation between accelerator systems under identical workloads. However, benchmark results rarely match your own model. Test a small production sample, measure tokens per second, startup time, and memory usage. Fast hardware is not always cheaper. A slower instance may deliver better cost per completed task. That matters.
Availability is regional. The 2024 Uptime Institute Global Data Center Survey continued to document operational outages and capacity pressure across data centers. Ask about capacity reservations, replacement procedures, and maintenance notices. Security deserves equal attention. The 2024 IBM Cost of a Data Breach Report placed the global average breach cost at 4.88 million dollars. Use encrypted storage, short-lived credentials, private networking, and strict tenant isolation. Logs should show who accessed each dataset. One weak permission can undermine an otherwise careful deployment. I would still verify isolation claims independently; provider documentation is useful, but it is not proof.
Choosing a GPU rental service starts with your workload, not the advertised hardware list. Training large models may require high-memory GPUs, while video rendering can prioritize speed and stable storage. Check memory capacity, supported frameworks, operating systems, and regional availability before comparing hourly prices. A cheaper instance may waste money if data transfers slowly or jobs restart unexpectedly.
Tips: Run a small benchmark with your own code. Measure setup time, processing speed, memory usage, and total cost. Ask about billing pauses, storage fees, cancellation rules, and support response times. Review security controls carefully, especially encryption, access permissions, audit logs, and data deletion policies. Clear documentation matters more than polished claims.
Reliability also depends on capacity during busy periods. Request historical uptime information when possible, and test whether the service offers backup regions or replacement instances. I once focused too heavily on GPU speed and overlooked storage performance. That mistake increased project time. A careful comparison should include real workload results, not only benchmark scores. Keep your first contract flexible. Needs change.